
AI Powered
Mixing Engine
Intelligent source separation and mixing engine powered by Demucs and MDX architectures. Isolate stems, apply genre-aware processing, and generate streaming-optimized mixes — at scale.
Precision controls. Powerful models.
Select the right separation model for every project, then fine-tune parameters to get the cleanest stems possible before mixing.
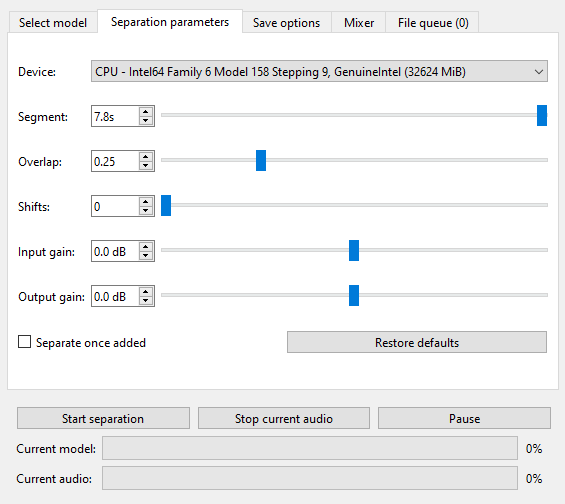
Model Selection — Demucs Architecture Chooser
Choose from htdemucs, hdemucs_mmi, htdemucs_6s, MDX, MDX Extra, MDX_q, and repro variants. Load local model signatures or pull from remote repositories for maximum flexibility.
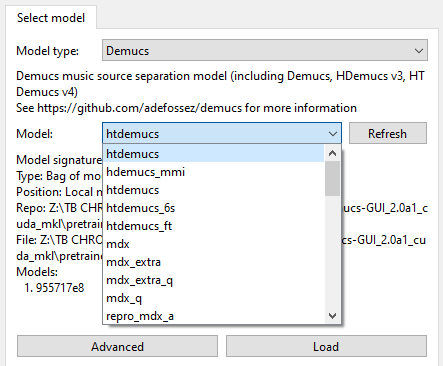
Separation Parameters — Device, Segment & Gain Control
Configure CPU/GPU device targeting, segment length (7.8s default), overlap, shifts, and input/output gain. Start, stop, or pause separation jobs with real-time per-model and per-audio progress tracking.
Built for professional audio operations.
AI-Driven Source Separation
Powered by Demucs, HTDemucs, and MDX model architectures. Isolate vocals, drums, bass, and other stems with state-of-the-art precision.
Fine-Grained Separation Parameters
Control segment length, overlap, shifts, input/output gain — all adjustable per session for optimal stem quality across genres.
Multi-Model Support
Switch between htdemucs, hdemucs_mmi, htdemucs_6s, MDX, MDX Extra, and repro models. Select the right architecture for each project.
Genre-Aware Processing
Intelligent mixing passes optimized for streaming loudness, clarity, and translation across consumer playback systems.
Batch File Queue
Queue multiple audio files for automated separation and mixing in sequence. Reduces manual overhead for high-volume catalog operations.
Flexible Save Options
Configure output formats, file naming conventions, and destination paths. Integrates into existing delivery pipelines.
Ready to automate your mixing workflow?
Contact our team to integrate the AI Powered Mixing Engine into your enterprise audio production pipeline.